
Mini Homelab Part 2: A Raspberry Pi 5 LLM Gateway with Hermes
Disclaimer: No AI was used in the writing of this post, all thoughts expressed, including mistakes and hallucinations, are my own.
I wanted to make an update post to document my experience using one of my raspberry pi:s as a Hermes LLM agent Gateway.
What is Hermes? Hermes is an open-source harness that can be used with a model of your choice. I connect mine with my OpenAI Pro subscription which gives it access to models such as GPT 5.6. It has memory and re-usable skills, which means it can write text files to the host system which act as “memories” that can be read and re-used later to keep track of things that have been in the context.
Interface I chose Telegram chat as my interface since it is very easy to create bots that can be used to link up with Hermes. There are other choices such as Discord, Slack etc. but this was the easiest to set up, and I also use Telegram for my Homelab alerts bot so why not.
Use-cases I use it mostly as kind of an async research agent, that also has some insights and “experience” regarding my preferences and circumstances. For example I might want to research buying a new mechanical keyboard:
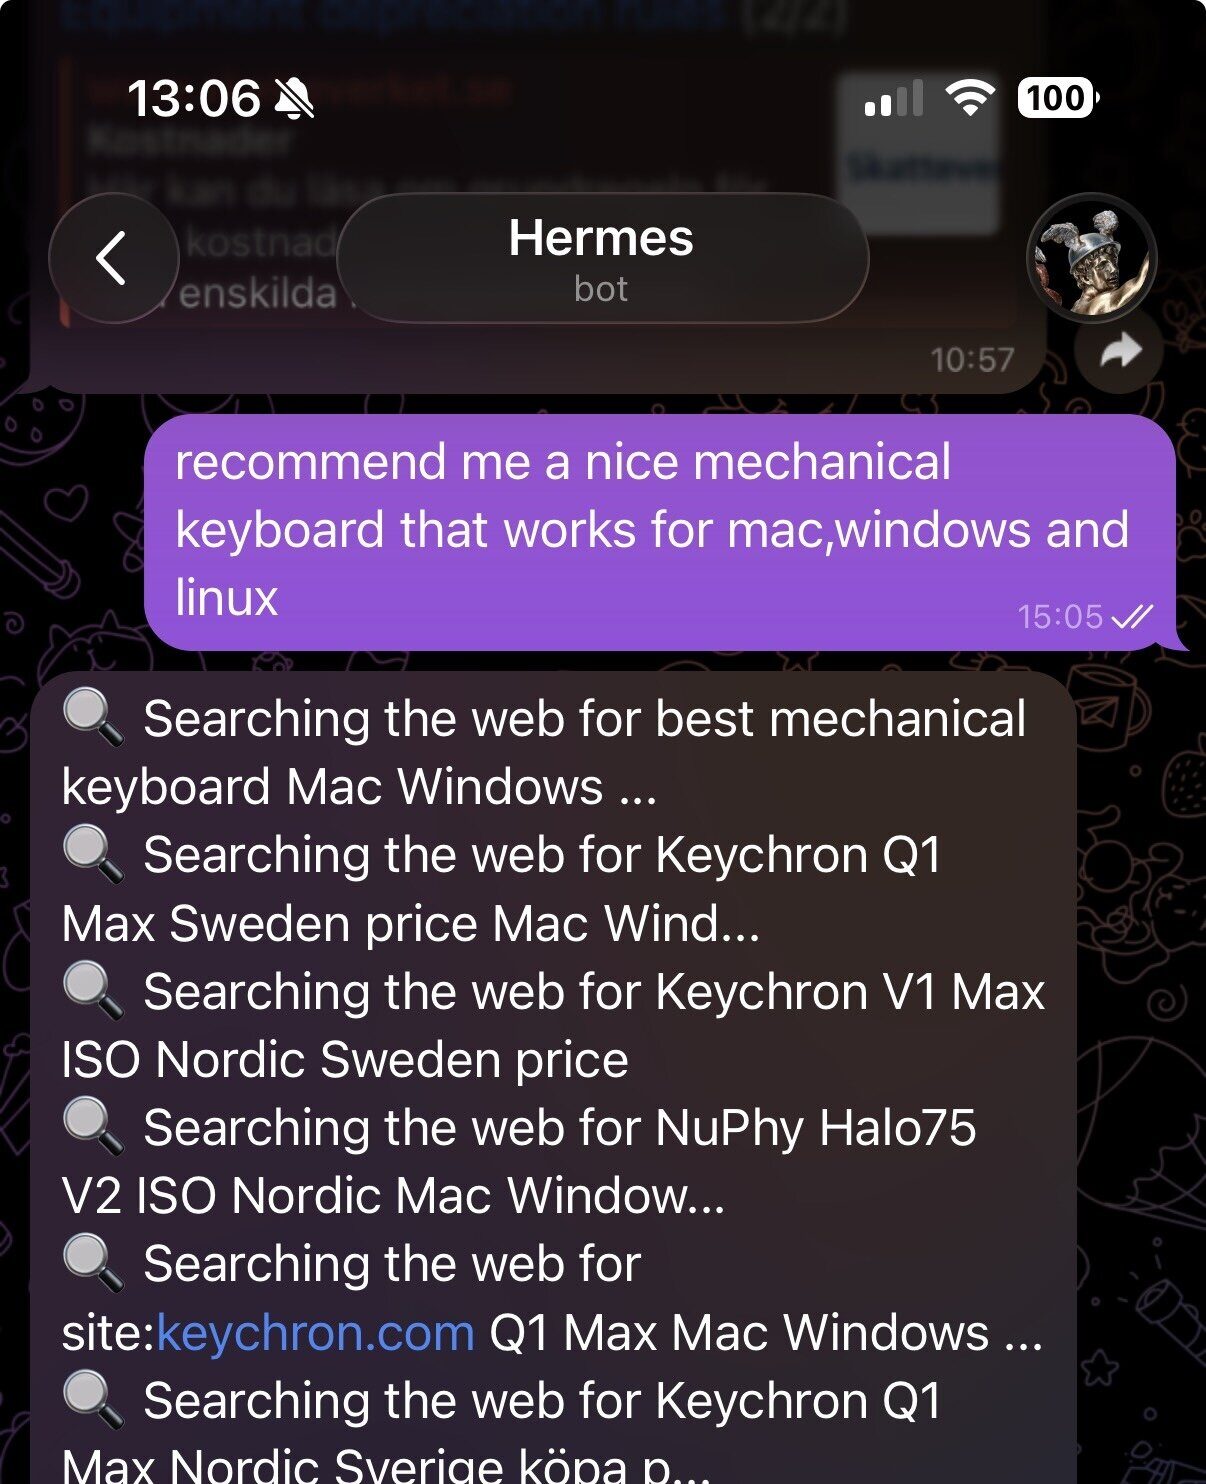
And it looks on the web for whatever it thinks is relevant based on the context (I want a mechanical keyboard, live in Sweden, etc.) and reports back.
I think researching products is a nice use-case, wether it be using a harness like this or gemini, since raw-dogging Google is fairly unusable for honest product research these days. And sure, the LLM might also pick up similar SEO-maxxed product listings but I’m betting that it does a decent job at least. And if OpenAI starts serving more products of a certain brand due to partnerships I can always switch models.
Why self-host? I think it’s a good idea to rely as little as possible on proprietary Frontier AI lab software these days. Given the incentives at play (maximizing shareholder value) nobody can predict the ways it could enshittify or who they might sell your data to for a quick cash-grab. At least I know now that all the important “memories” and other data and skills are stored locally on my machine. Sure, I also send personal data as tokens to the actual LLM endpoints for processing, but at the very least I can choose freely which LLM endpoint to use without any pain on my side. And if I manage to set up a local inference machine I can hot-swap to that endpoint whenever.